
Stand by what you ship
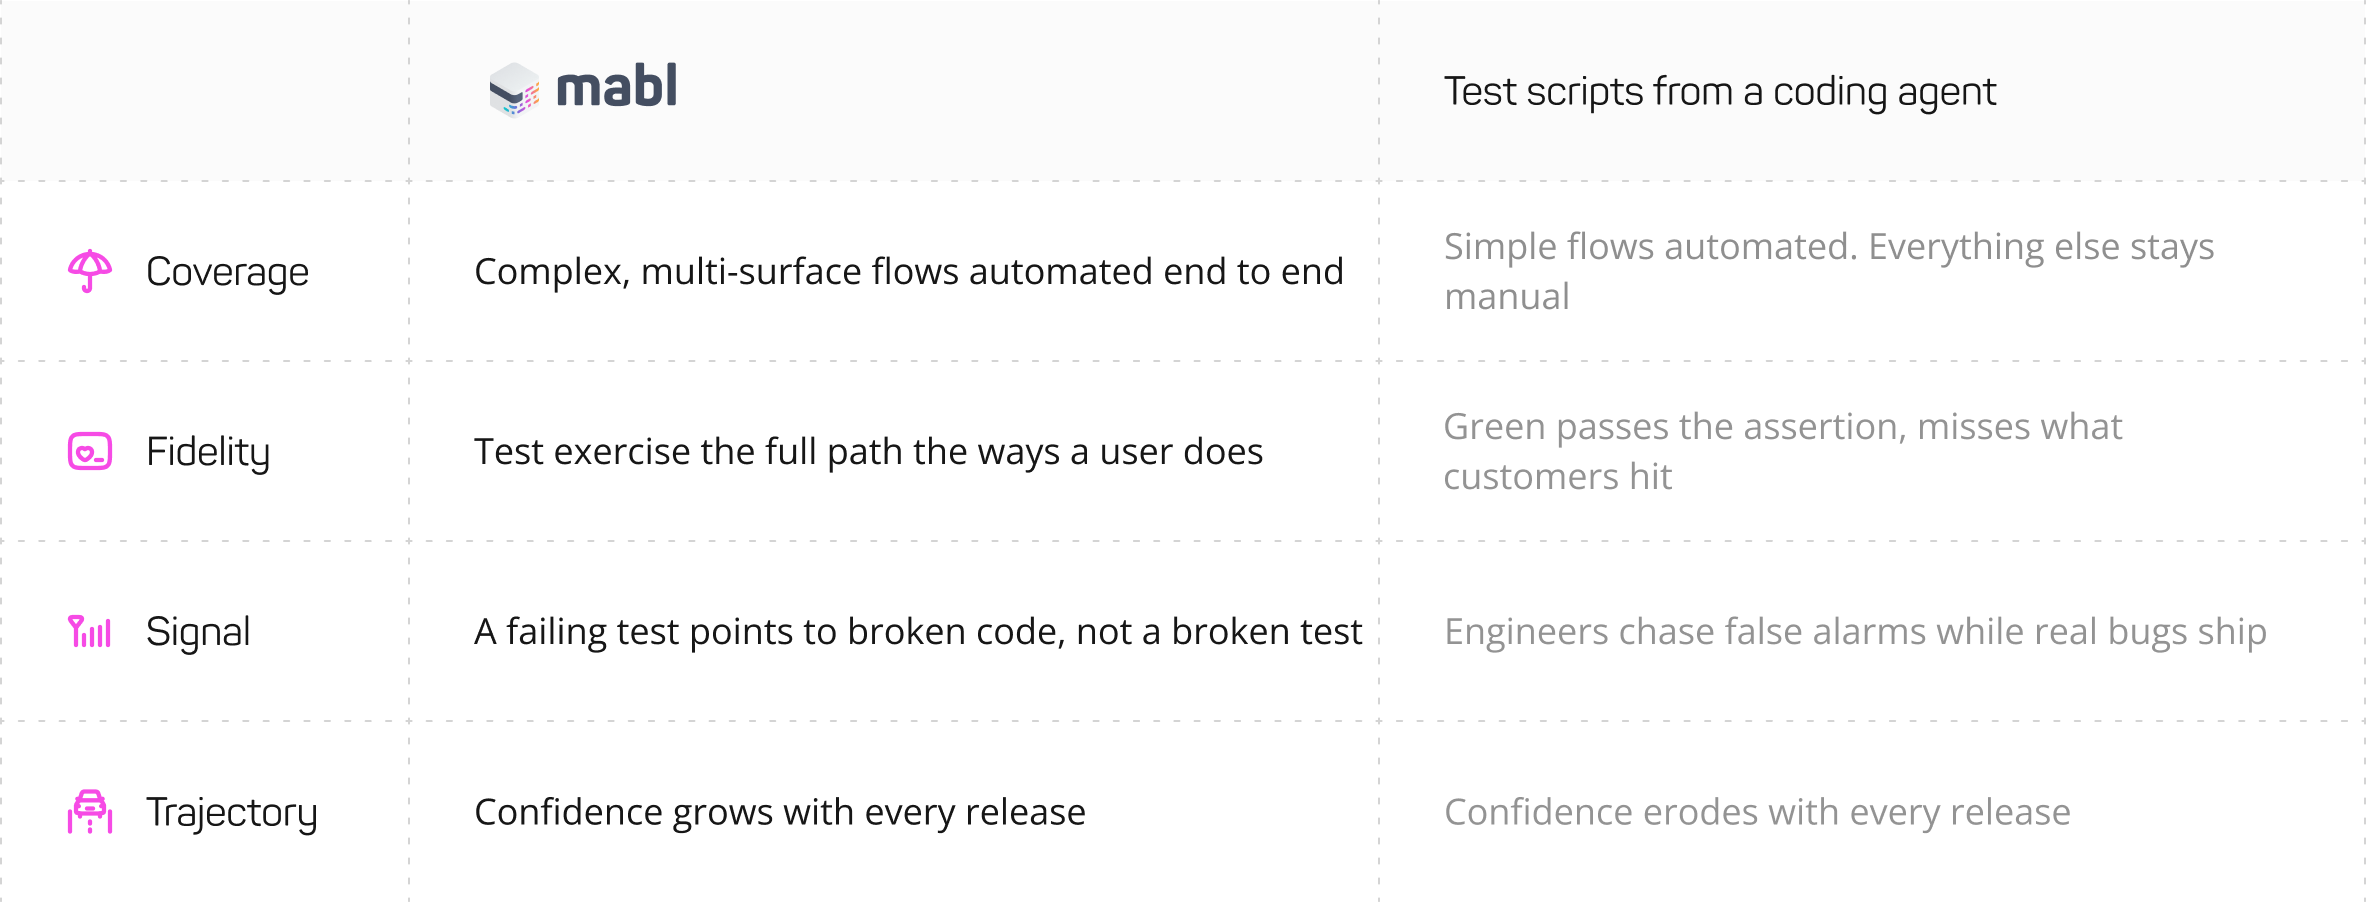
All your complex workflows, automated end-to-end
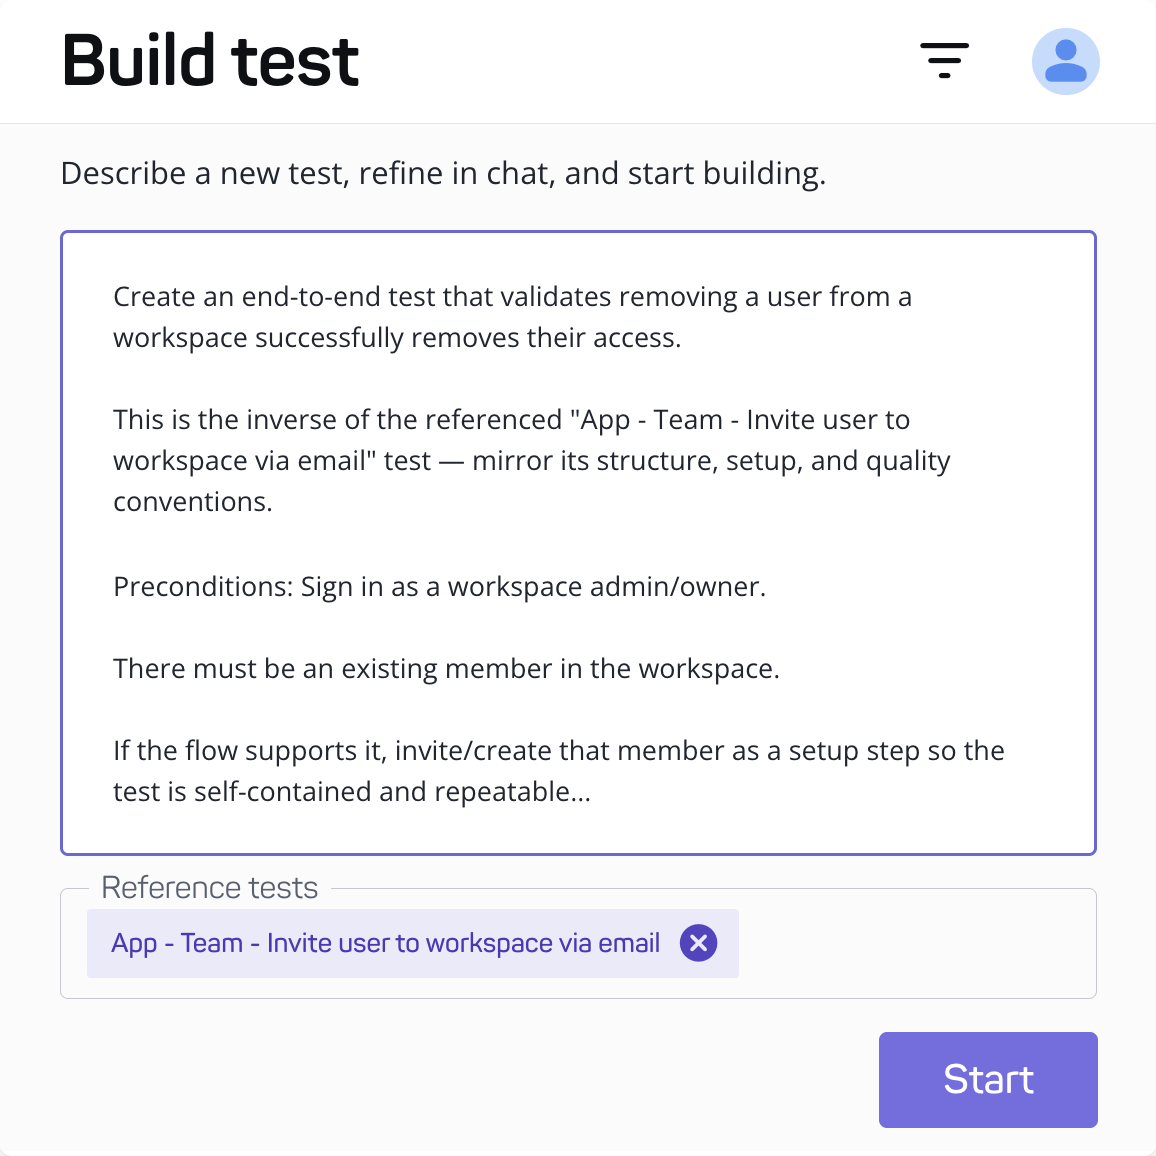
Agentic test generation
Create reliable tests from natural language intent and your agent’s context, validated to work.
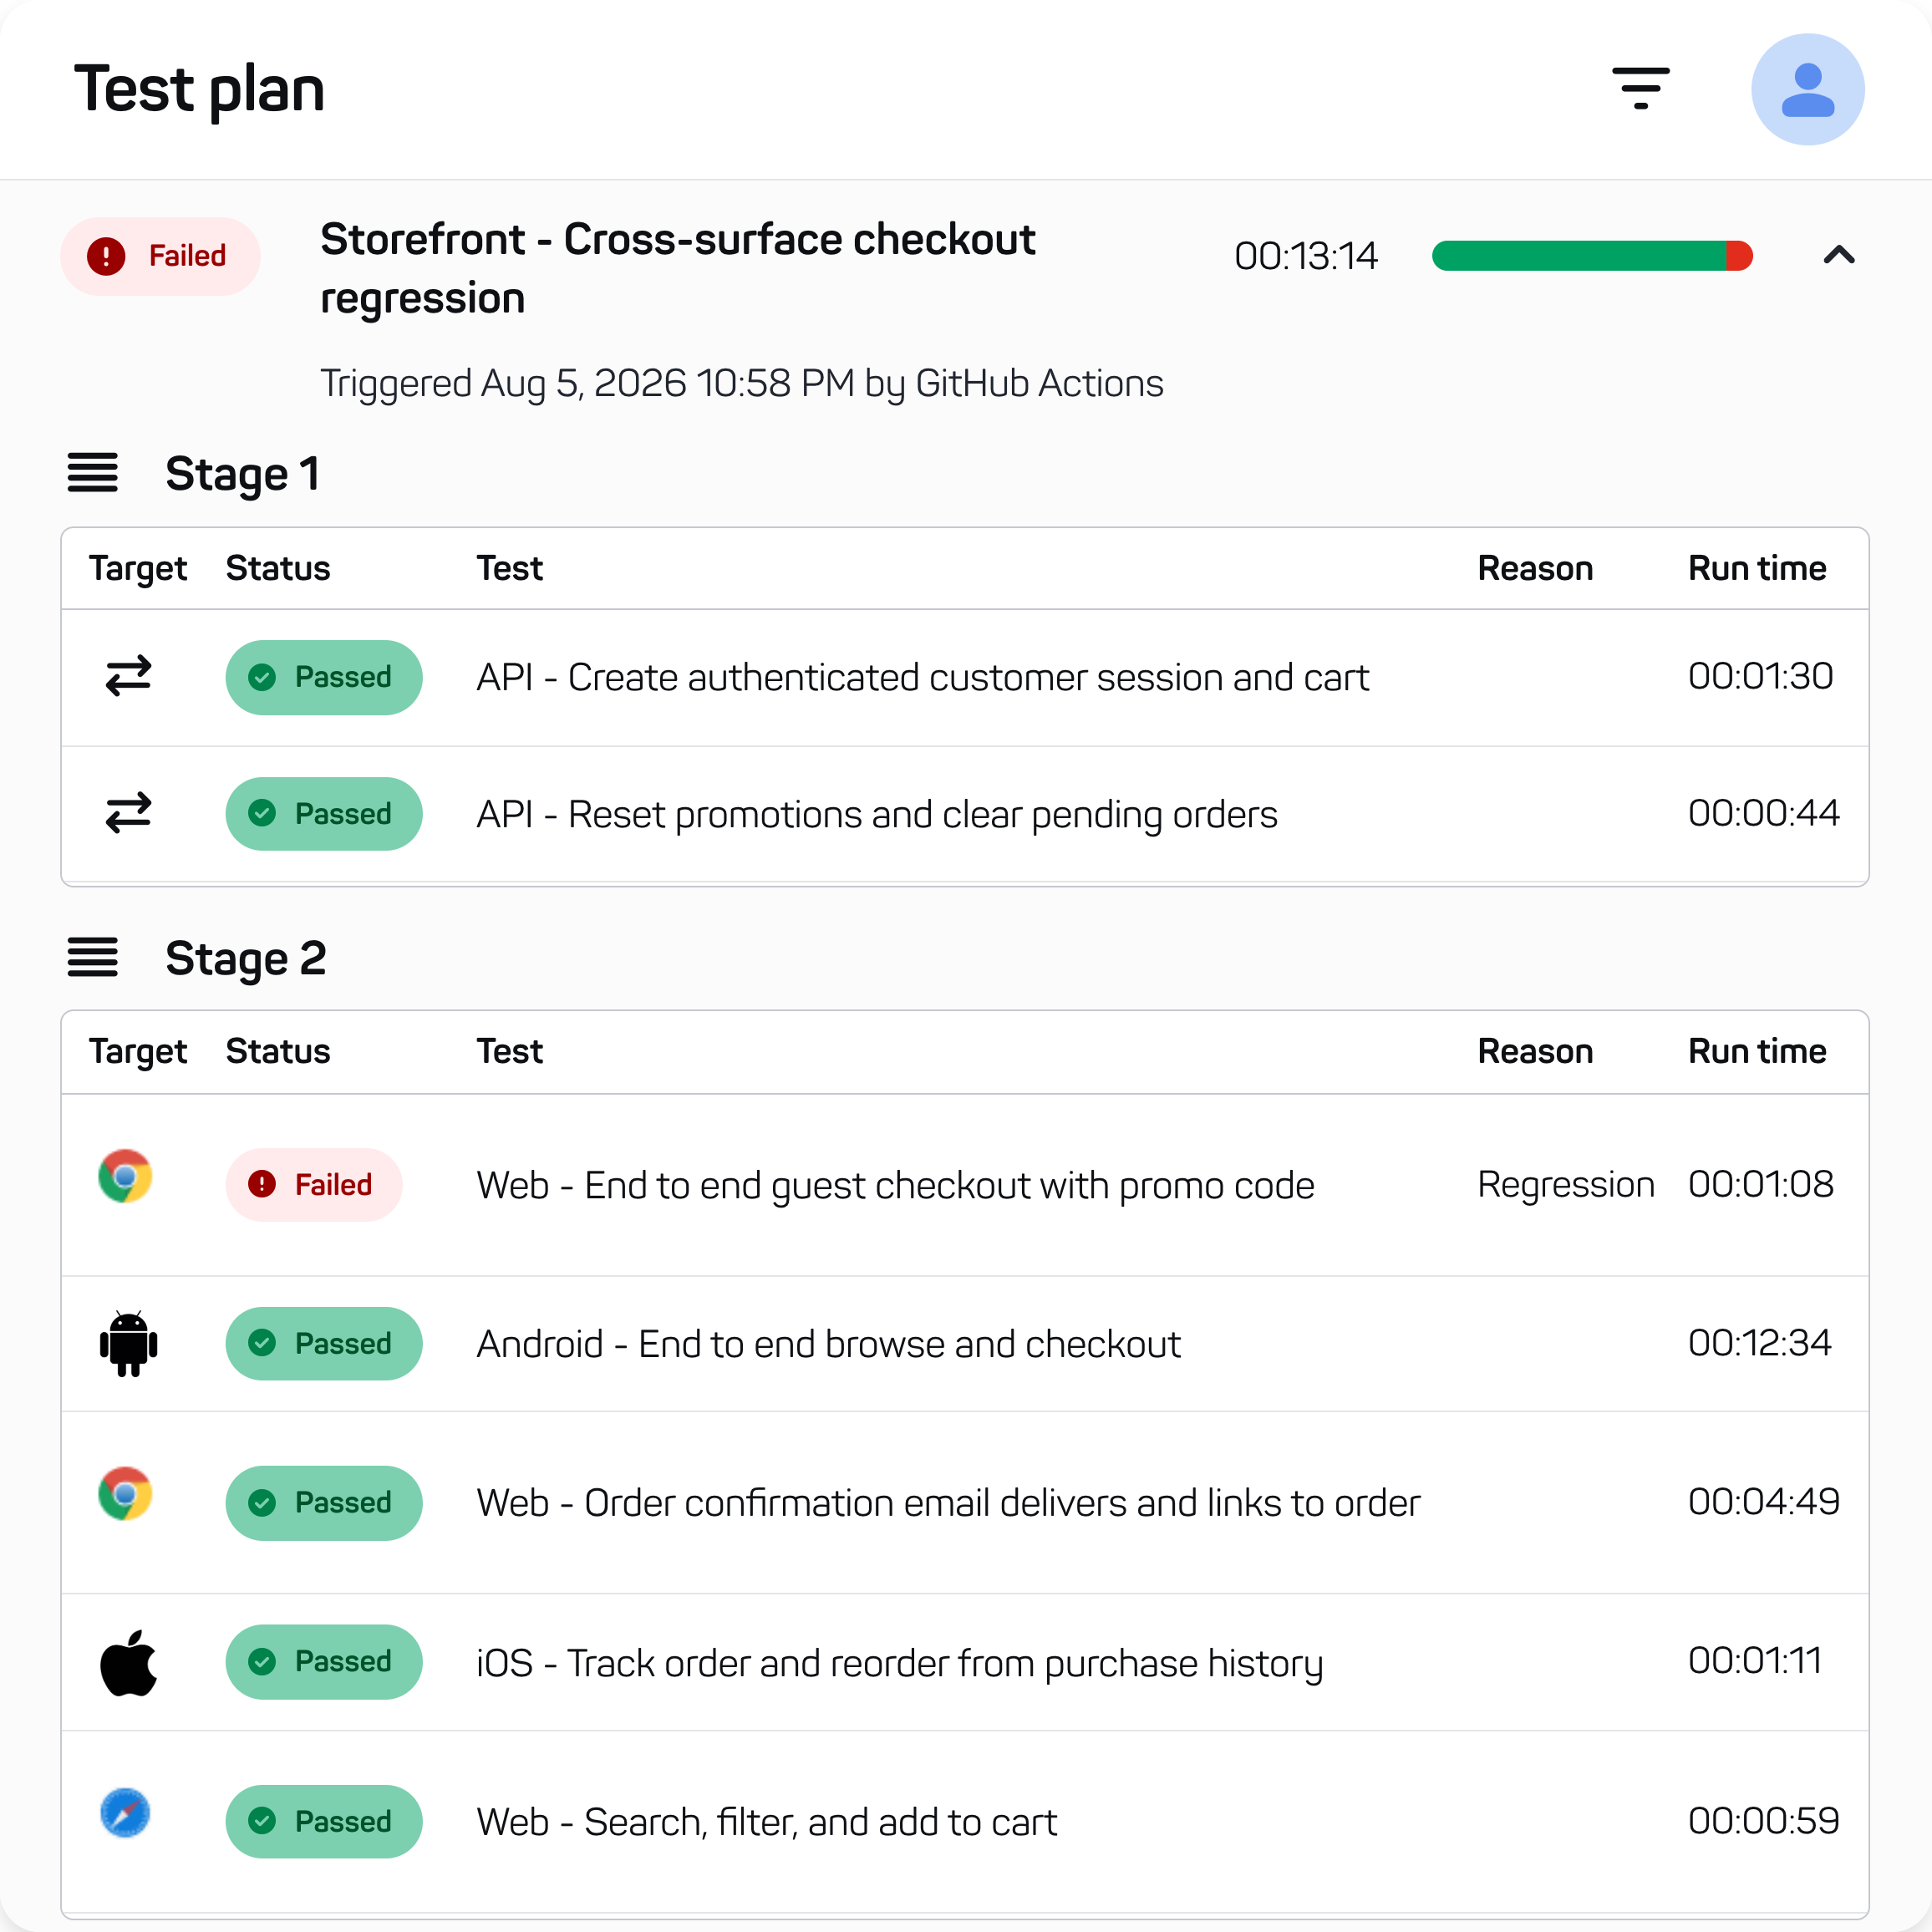
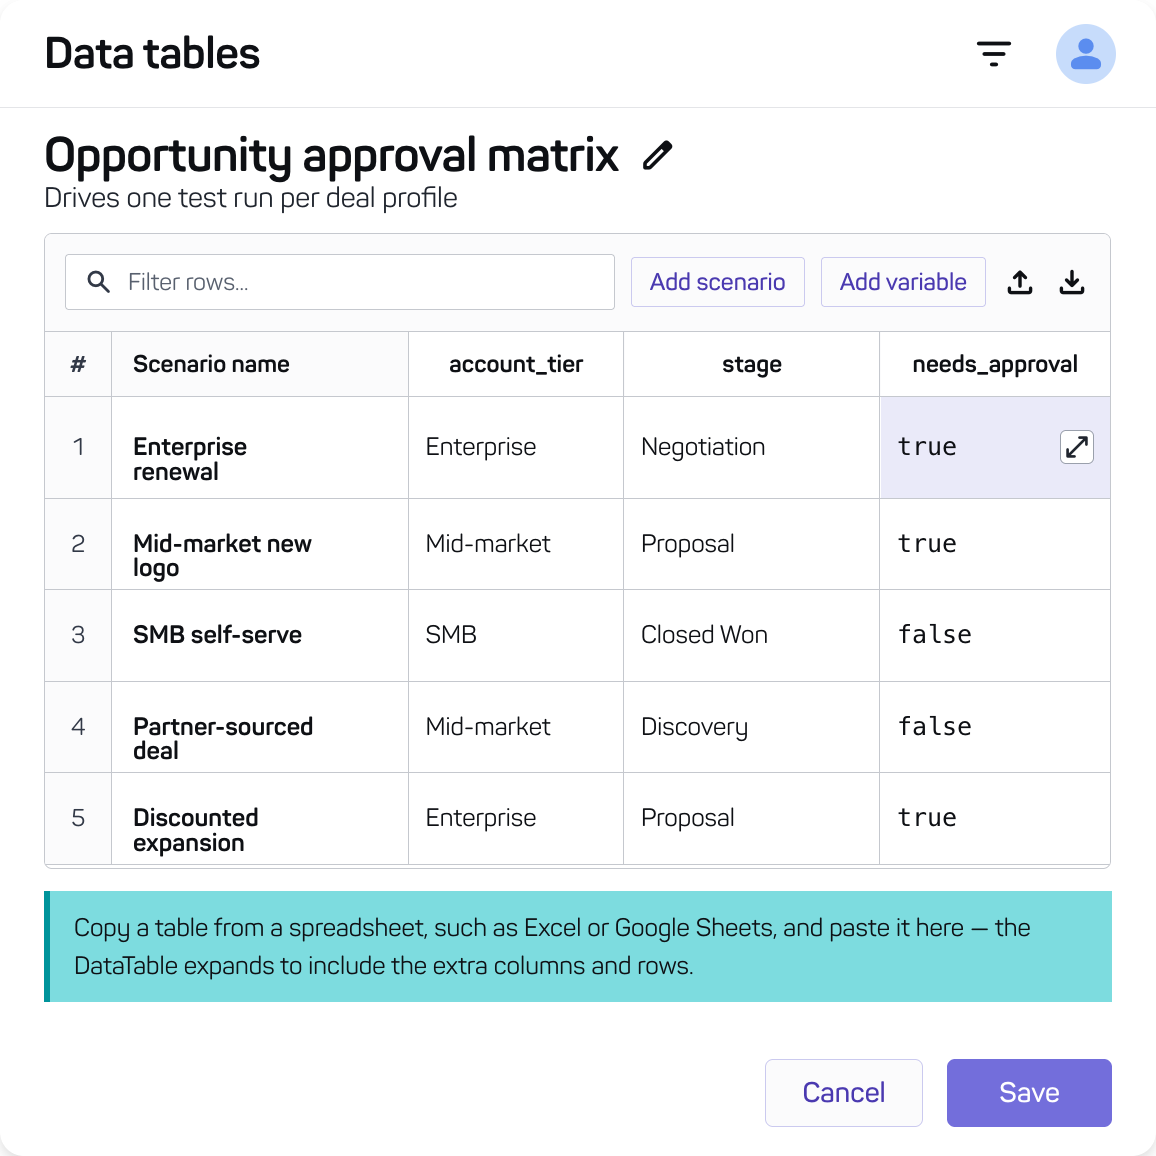
Web, API, and mobile testing
Cover all your app surfaces, instead of stitching together tools and frameworks.
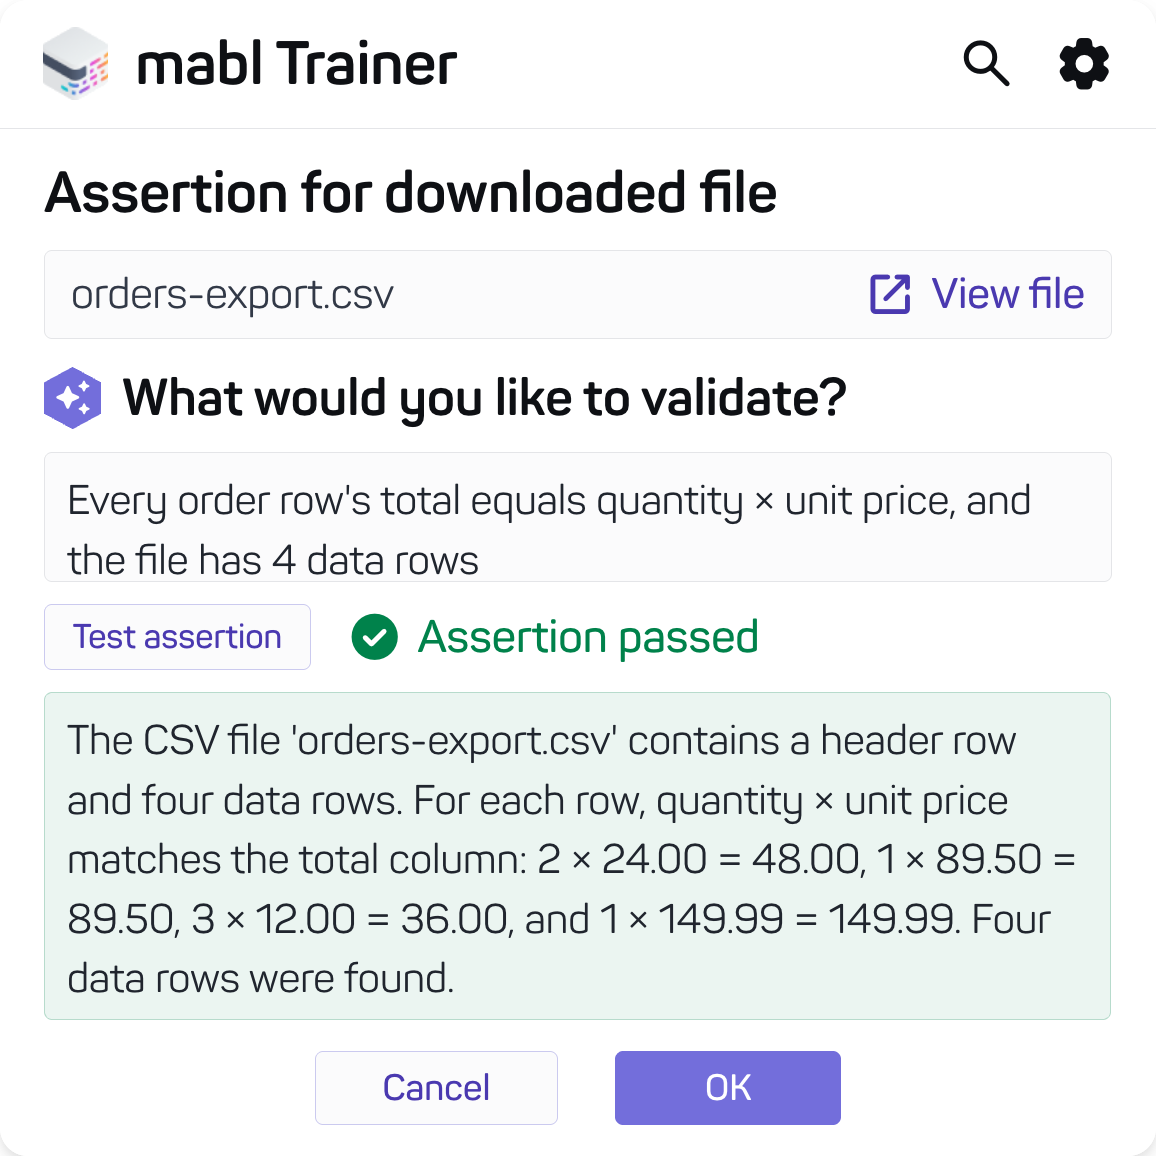
Email, file, and database validation
Automate the validation of email workflows, file content, and database accuracy.
Test like real users, at scale
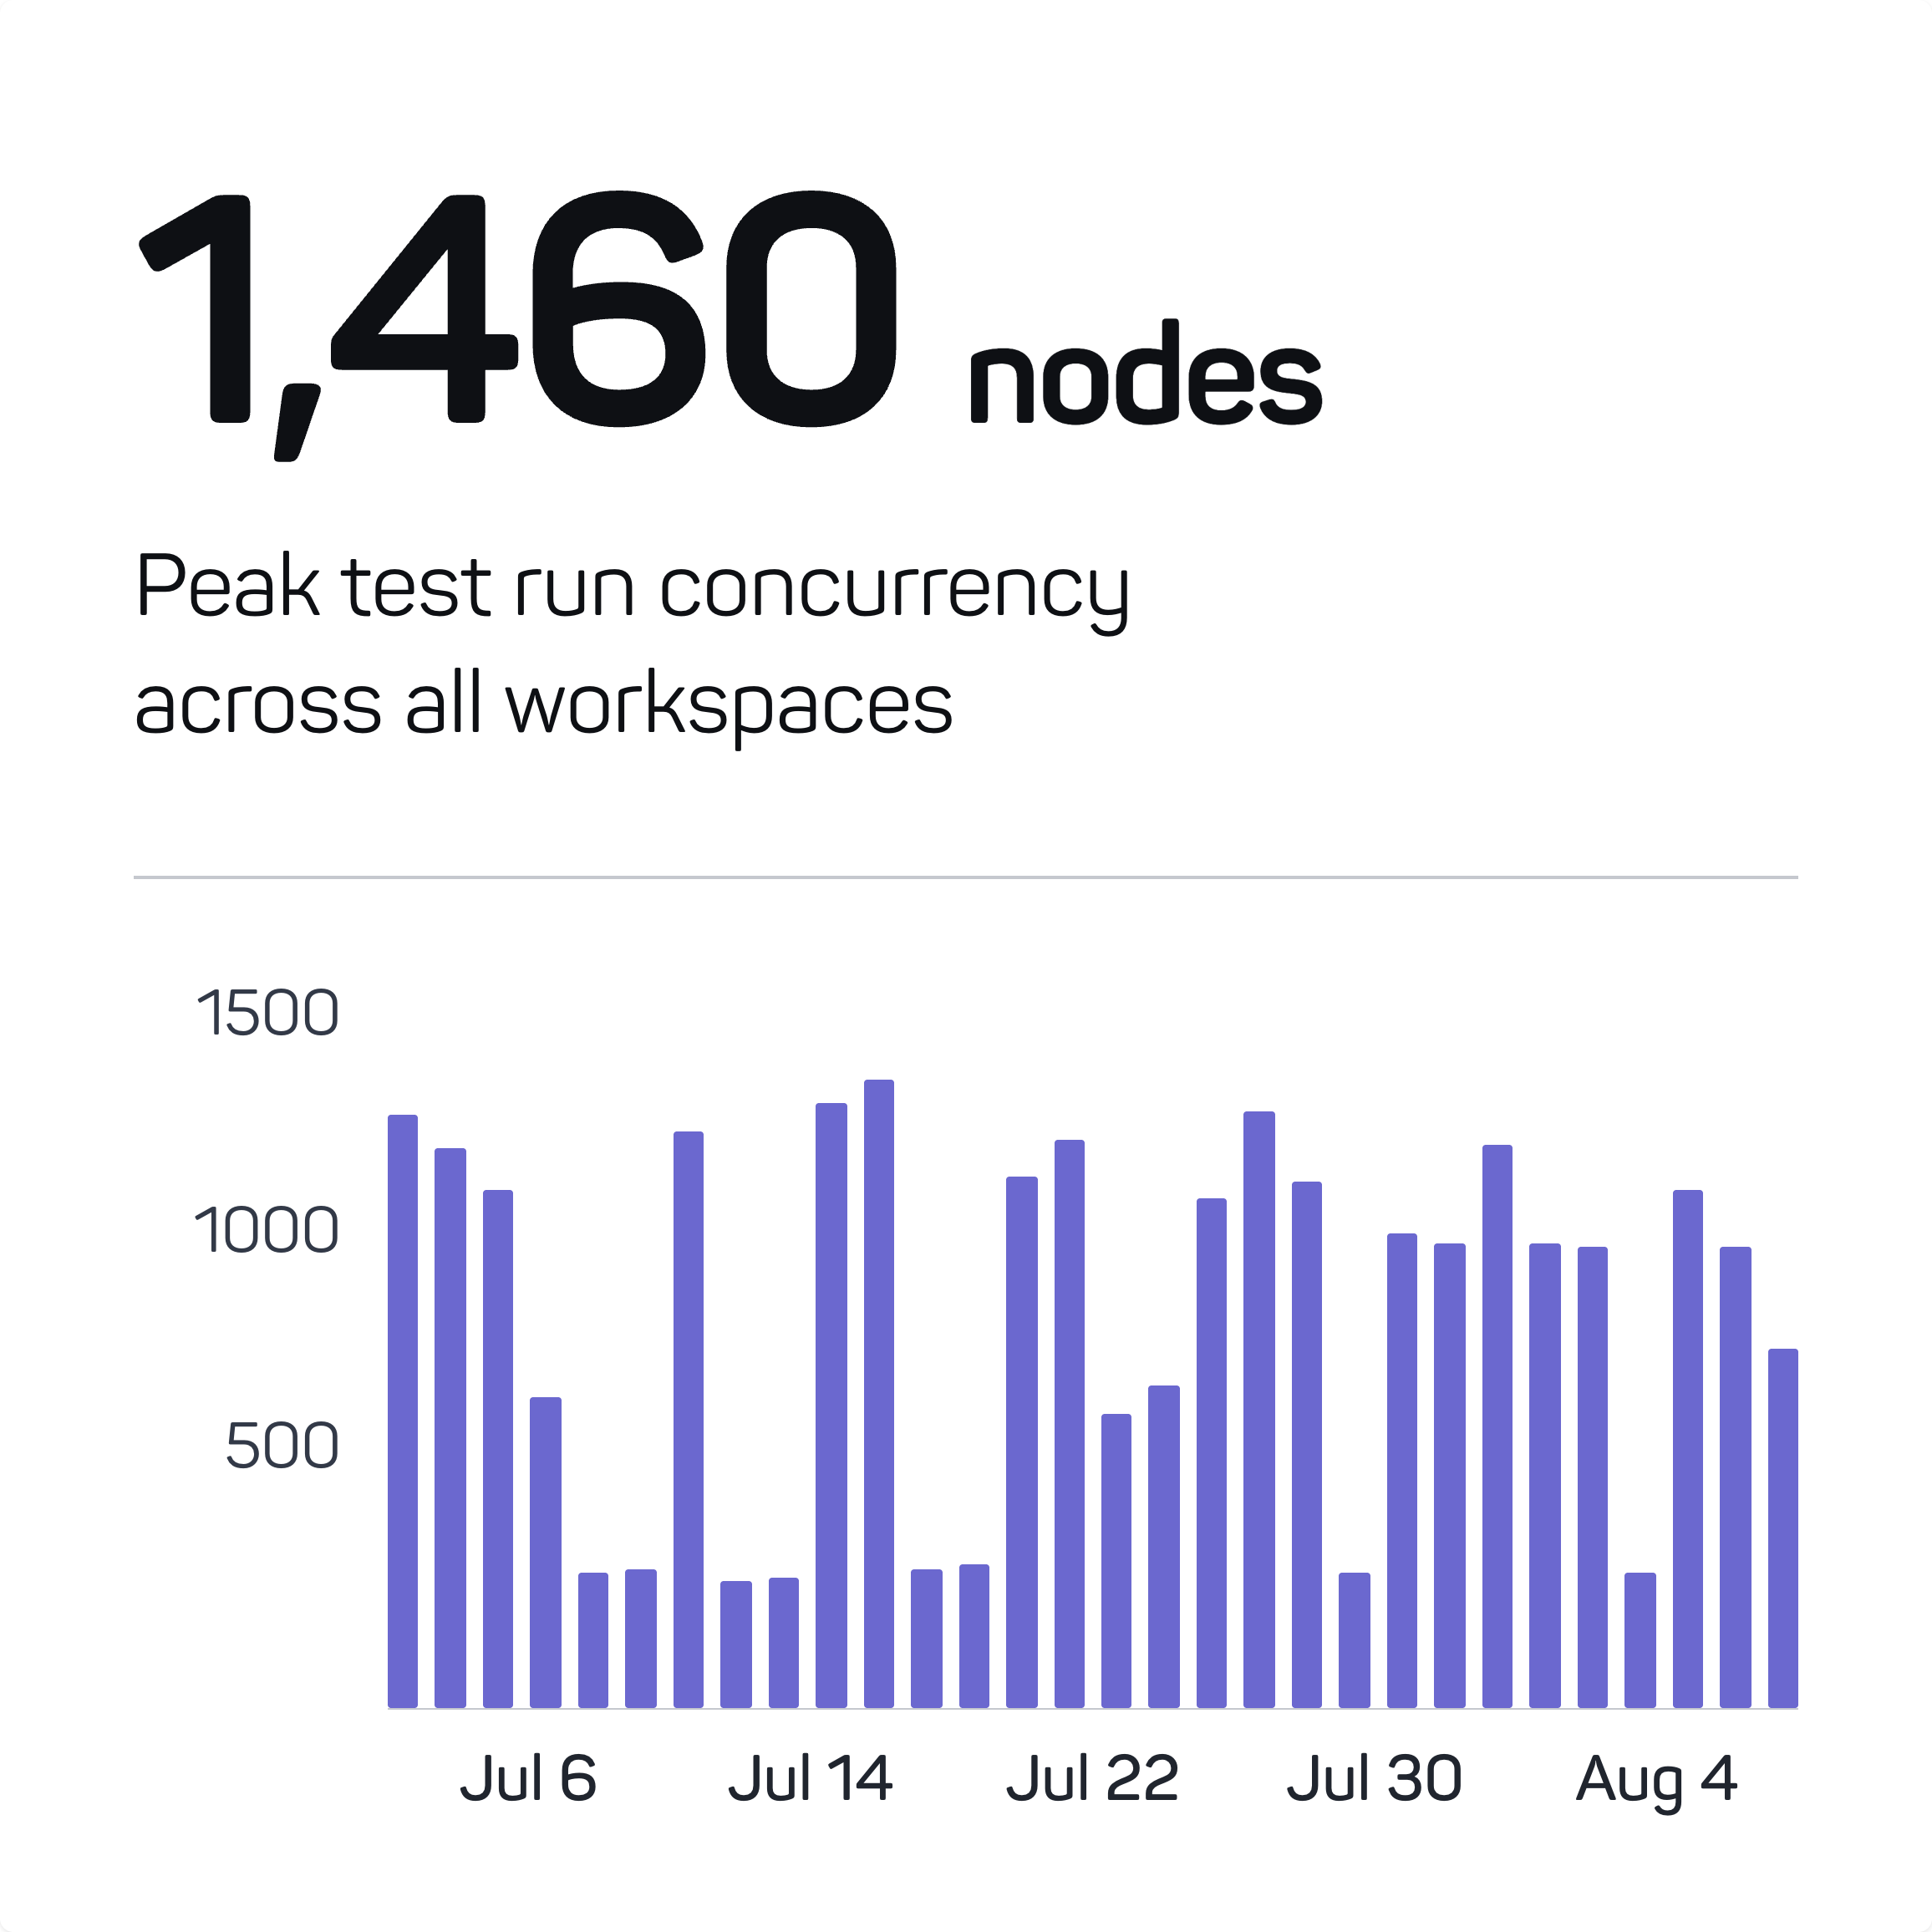
Unlimited parallelization
Execute thousands of tests in the mabl cloud for fast results from large test suites.
Visual finds and assertions
Define test actions and assertions with natural language, without relying on DOM content alone.
Trust the signal, remove the noise
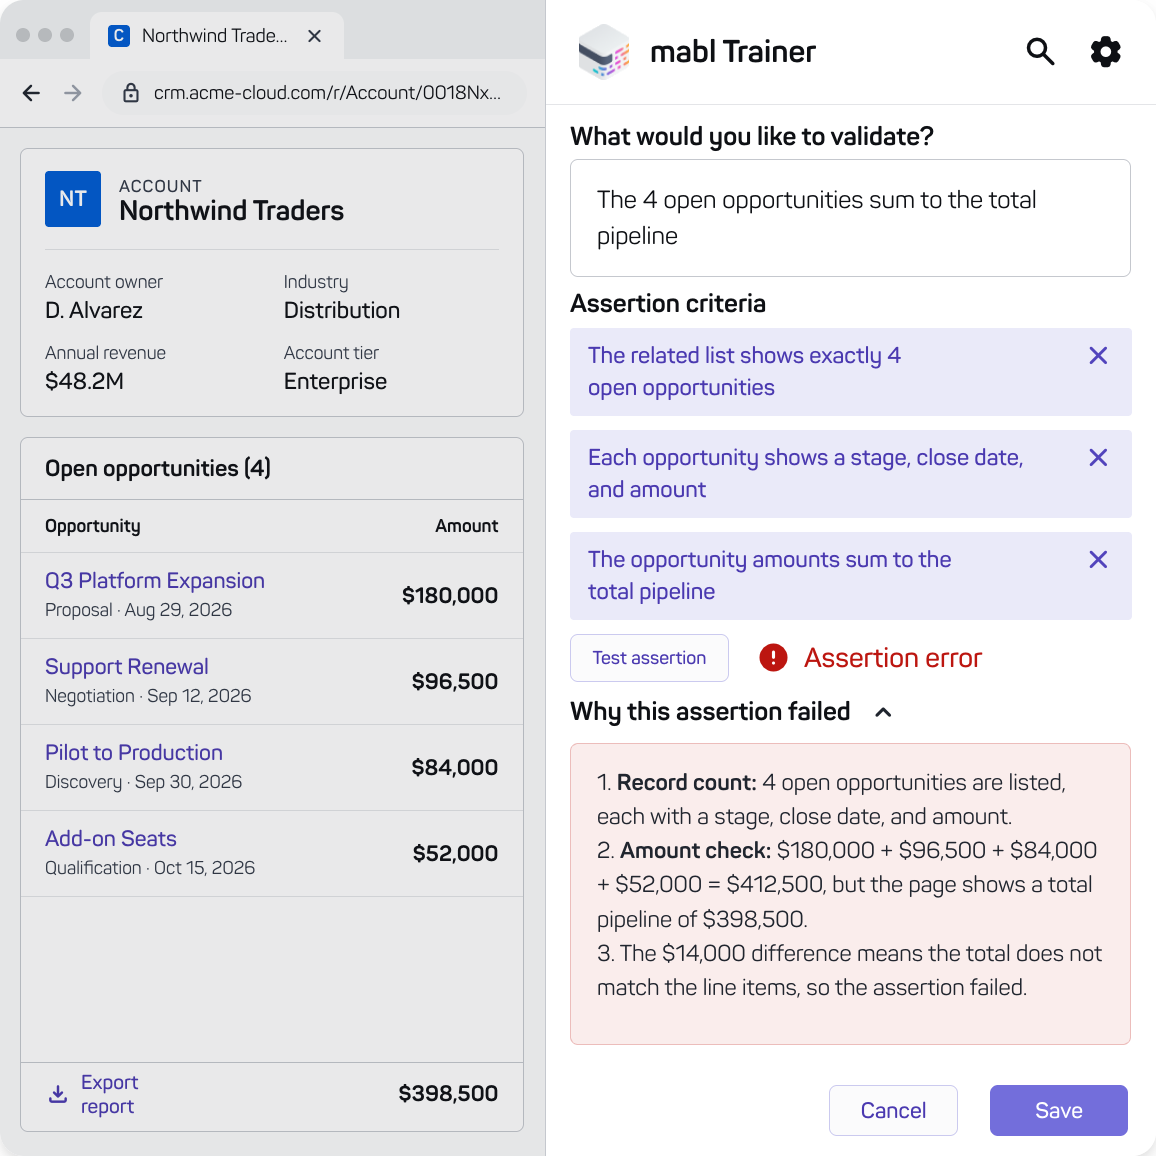
Agentic failure analysis
Every failed run returns an explanation with evidence and recommendations, optimized for agent consumption.
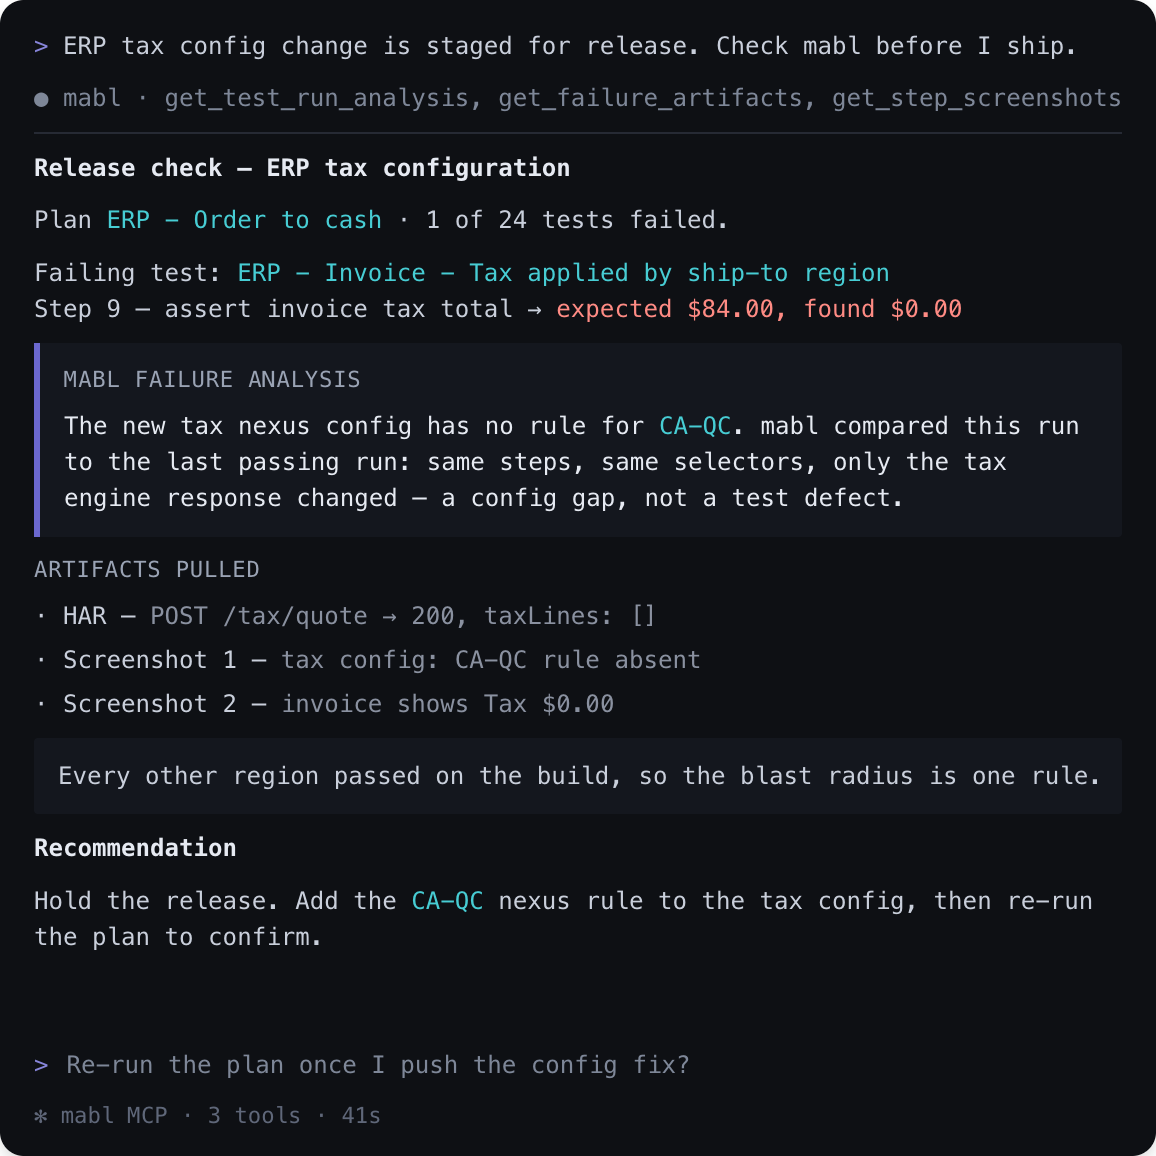
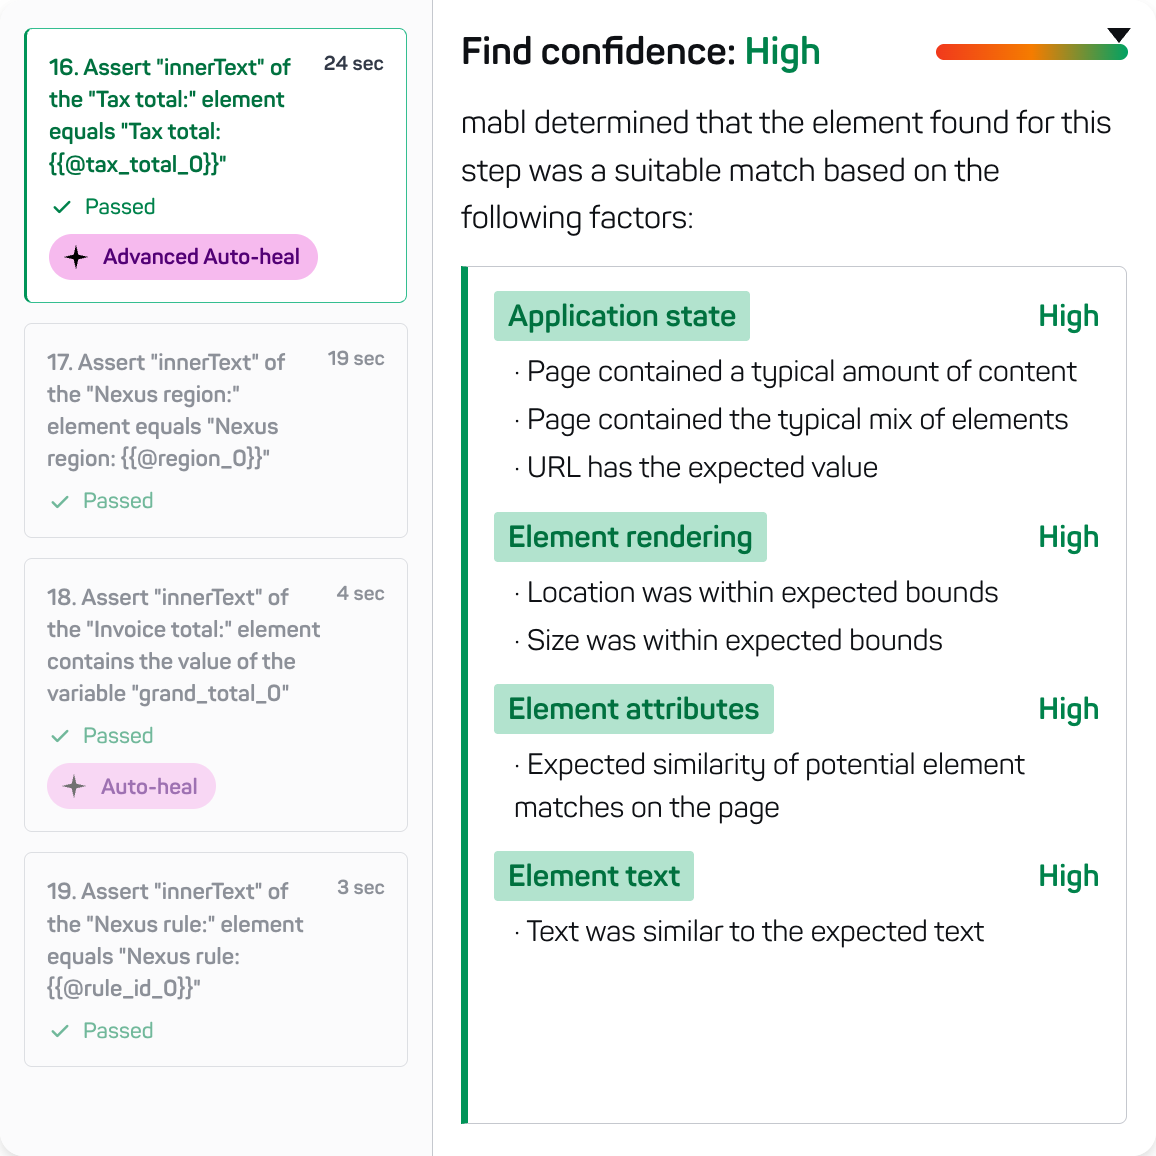
Agentic auto-healing
Instead of failing, tests adjust to unexpected selector changes and UI shifts while preserving intent.
Test reliability reporting
Understand and track test suite health to eliminate time spent on false alarms.
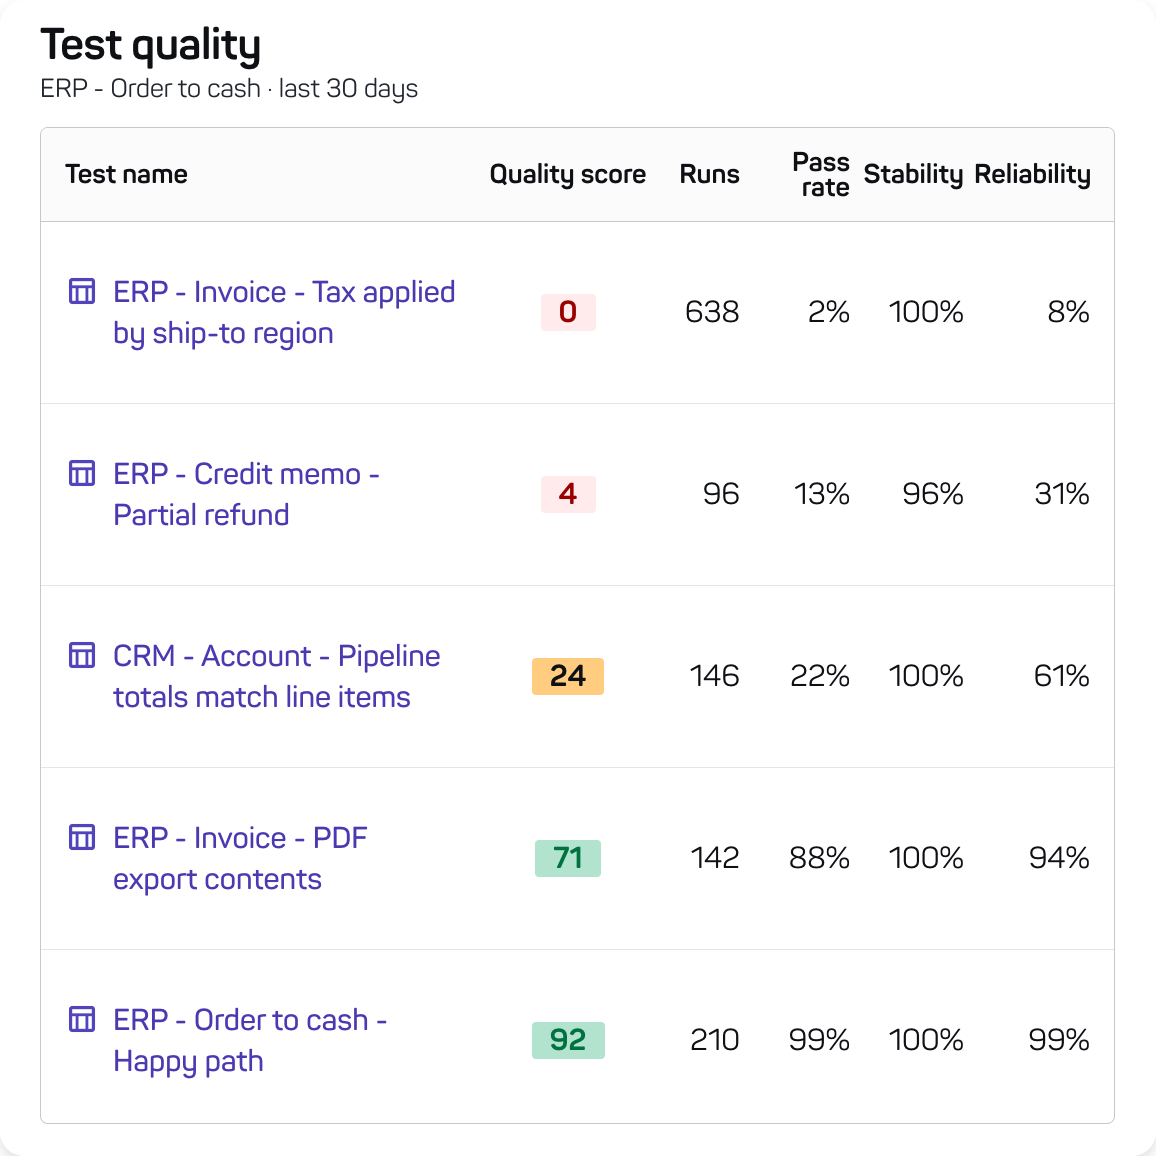
Reliable insights into your release quality
Precise, change-aware quality signals that understand your business and application context.
-
Read the Leading Reach customer story
0
Bugs in production
-
Read the Priceline customer story
100,000
E2E tests running each month
-
Read the SealingTech customer story
86%
Reduction in test execution time
-
10x
Faster test creation
-
Read the JetBlue customer story
9x
Faster test execution
-
Read the Momentum energy customer story
90%
Less time spent on suite maintenance
-
Read the Priceline customer story
80%
Coverage on core features
-
Read the LeadingReach customer story
2x
Faster releases


