アプリが変わっても、手直しを最小限に抑えるテスト自動化

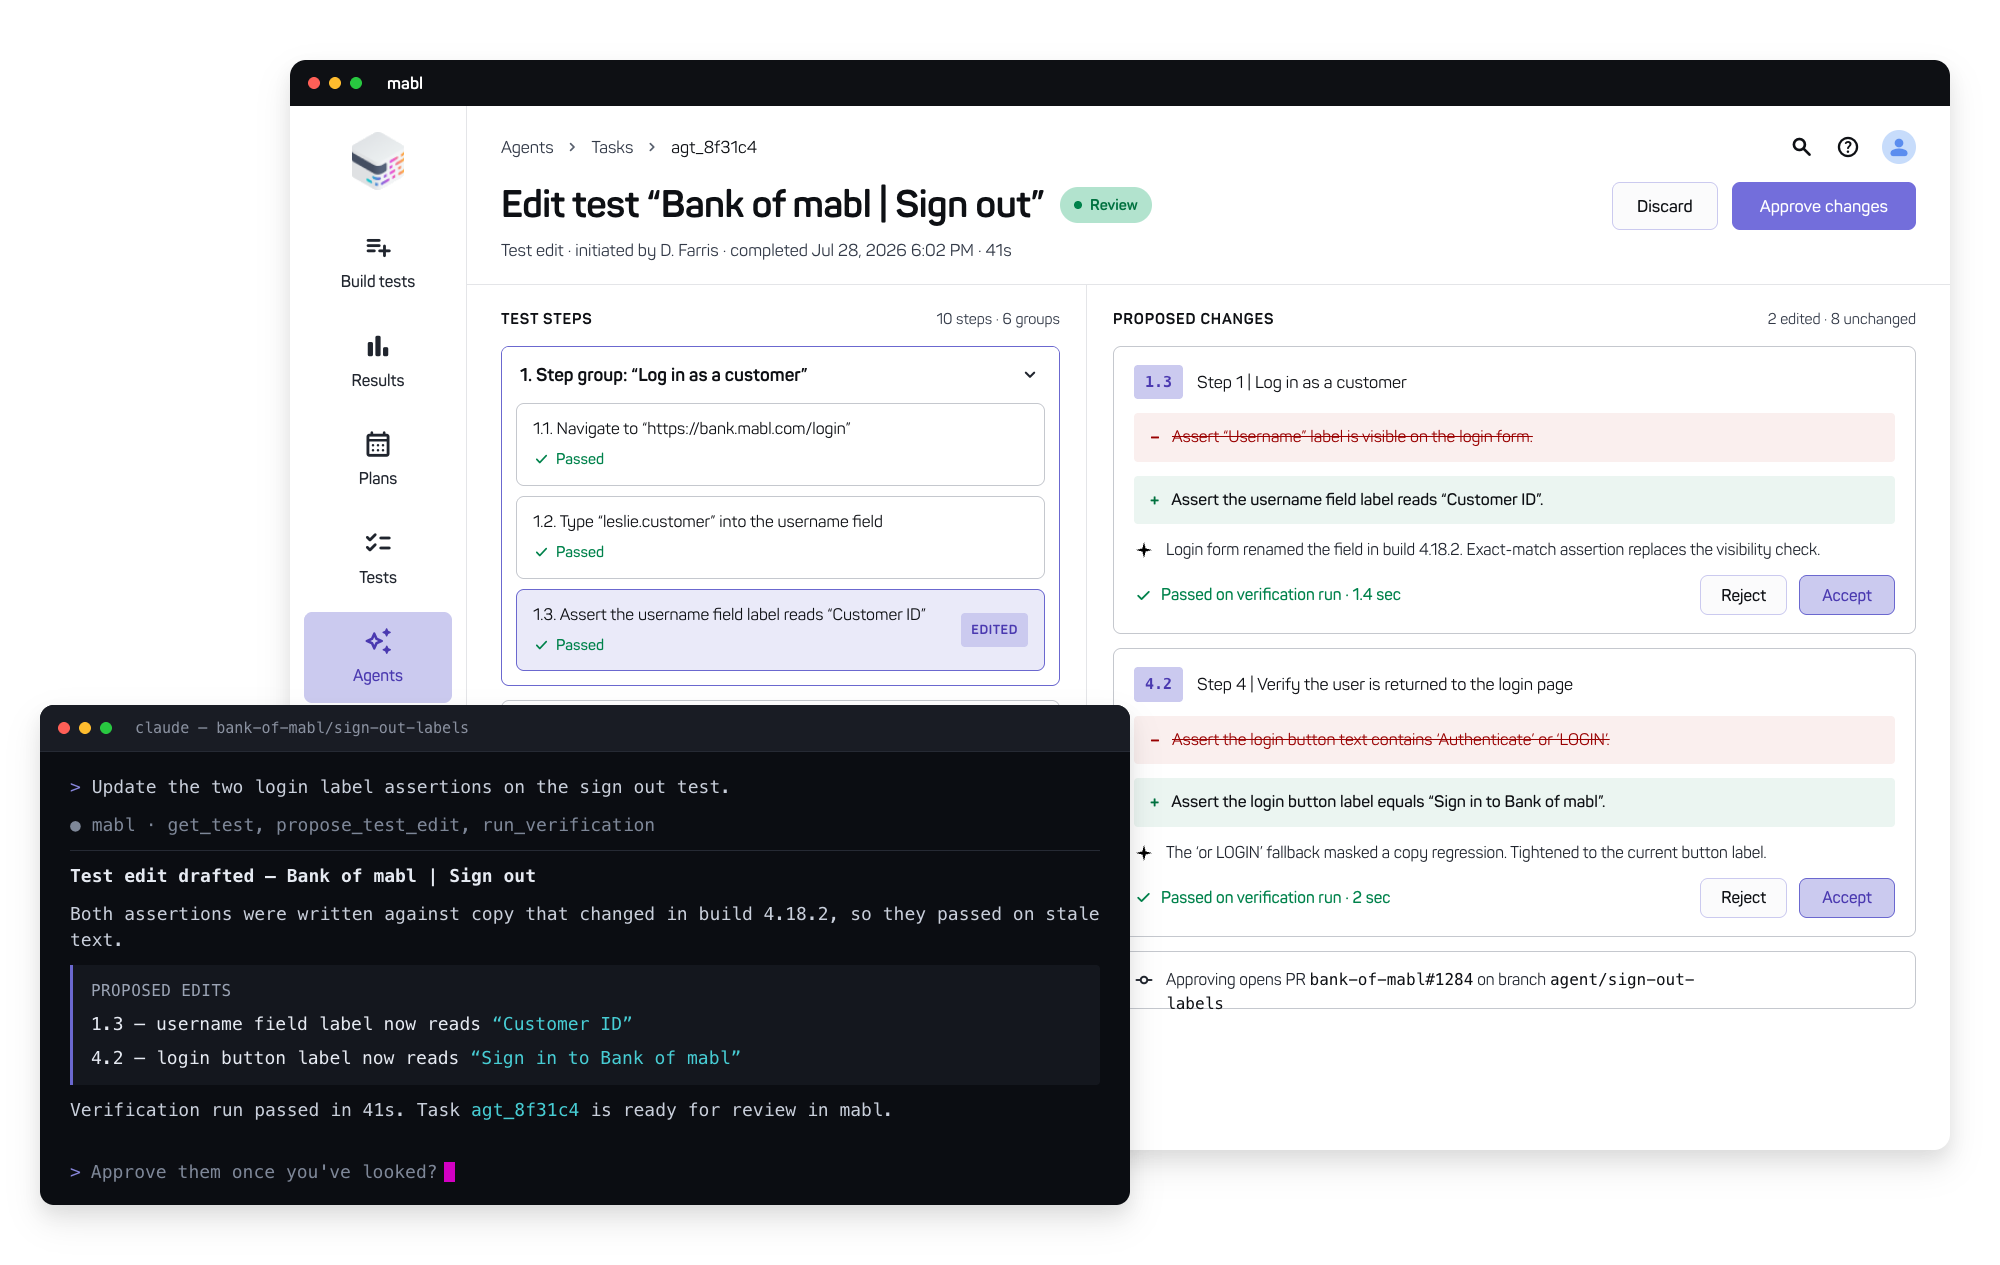
Agent task review hero-selection

The world's most advanced testing harness

The engineering underneath: independent, reliable, resilient.

  • Per-task LLM routing

    The best model for each testing job. You don't need to worry about upgrades, prompt rewrites, version pinning, or evals.

  • Reliable tools for your agent

    An MCP for the full testing loop. Broad tool coverage, progressive disclosure, idempotent writes, token-efficient, streaming with keepalive, OAuth.

  • Self-healing off a model, not a selector

    Every element is modeled as dozens of weighted attributes, so a page change re-identifies it by best overall match, falling back to locating it visually when attributes aren't enough.

  • Structural objectivity

    An LLM told to make a test pass will edit the DOM or weaken the assertion to get there. mabl runs your deployed app in a real browser, in a separate context, and checks it against assertions you defined separately.

  • Your intent, translated

    You describe what to test and set your guardrails; mabl's tuned metaprompts turn that into the structured instructions the agent runs on, scoped per agent with mabl's own guardrails winning on conflict. You get an effective agent without prompt-engineering it yourself.

  • Deterministic first, LLM when needed

    Cheap deterministic locators run first; the model engages only when they fail. More efficiency, lower cost, faster.

壊れにくいテストに任せる

マルチシグナルの要素特定モデル

要素の属性と過去の特定履歴をもとに要素を識別し、DOMの情報だけでは不十分な場合は視覚的な説明で特定します

詳しく見る

エージェントによる自動修復

予期しないセレクターの変更やUIの変化があっても、本来の意図を崩すことなくテストは成功し続けます。

詳しく見る

インテリジェントウェイト

アプリの過去の読み込み状況をもとに、安定して操作可能な状態になるまで待機。固定の待機ステップに頼ることなく、読み込み完了前に検証が進んでテストが失敗するのを回避します。

詳しく見る

本当の問題を、すばやく修正

対話型の結果分析

修正につなげやすい分析と推奨対応で、テストの失敗をすばやく把握できます。

詳しく見る

エージェントによるテスト編集

整理された失敗分析をコンテキストとして使い、人に指示するような言葉で、エージェントまたはUIからテストを更新できます。

詳しく見る

エージェントに対する指示

テストを作成・更新する際のルールを状況ごとに定義し、一元管理できます。これにより、チームのベストプラクティスを踏まえた形で、エージェントにテストを作成・更新させることができます。

詳しく見る

傾向をモニタリングし、対応する

品質スコアのレポート

成功率・安定性・信頼性を組み合わせた総合品質スコアで、不安定なテストや壊れたテストがひと目でわかります。

詳しく見る

失敗の自動分類

結果は失敗カテゴリごとに自動でラベル付けされます。このラベル付けは、mablが定義したカテゴリに加えて、チームで追加したカテゴリにも適用可能です。

詳しく見る

スイートの健全性モニタリング

アプリ、環境、チームをまたいで、成功率・安定性・パフォーマンスを追跡します。

詳しく見る

チームが手直しに追われることなく、大規模なテストスイートを保守し続けるテストハーネス

失敗分析、自動トリアージ、エージェントによるテスト編集、そして業界で最も先進的な自動修復を、スケーラブルに統合します。

テストの手直しにかかる時間を86%削減

Frequently Asked Questions

+

How do you reduce test automation maintenance?

Most maintenance comes from brittle locators, hard-coded waits, and failures that take too long to diagnose. Fixing those three cuts the upkeep. mabl identifies elements from multiple signals, waits based on your app’s real loading behavior, and auto-heals tests through selector and UI changes.

+

How does self-healing test automation work?

Self-healing test automation detects when an element moves or its selector changes, finds the new target, and updates the test while keeping its original intent. mabl inspects element attributes and find history, falling back to a visual description when DOM signals aren’t enough.

+

How do you find flaky tests in a large test suite?

Track each test’s pass rate and stability over time, not just its latest result. Tests that alternate between passing and failing on unchanged code are flaky. mabl’s quality scores combine pass rate, stability, and reliability, so flaky and broken tests stand out quickly.